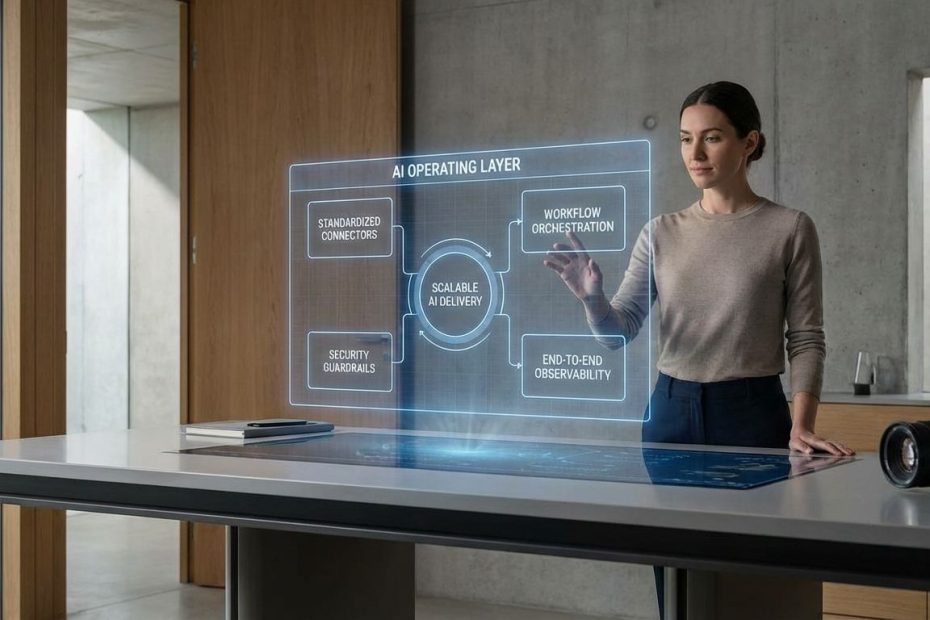
An AI operating layer wins when it turns raw model calls into a reliable production runtime: tool access you can govern, behavior you can measure, and systems you can scale across teams without rebuilding the same glue every quarter. Build it by standardizing connectors, orchestration, guardrails, and observability so every new AI workflow ships faster, safer, and with lower operating cost.
This article gives you a build plan that works in real organizations: what an AI operating layer is, what has to live inside it, how to stand it up in 30–90 days, where agent orchestration fits, which security controls stay non-negotiable, and how to prove ROI with metrics that survive exec scrutiny. You will leave with a practical target architecture, implementation sequencing, and operating rules that make quality repeatable.
What Is An “AI Operating Layer,” And How Is It Different From A Chatbot App?
A chatbot app is a product surface: a UI, a prompt, a model, and maybe a retrieval step. An AI operating layer is the runtime underneath multiple AI experiences: it controls how models get data, how they use tools, how their outputs get checked, and how every action is logged.
You build this layer when the organization crosses a threshold where “one good assistant” stops being the goal. The real goal becomes consistent delivery across many workflows: customer support triage, knowledge search, ticket handling, sales operations, engineering enablement, and internal approvals. Without a shared operating layer, each team invents its own patterns for RAG, tool calling, authentication, safety filters, and monitoring, then reliability drifts and costs climb.
From an engineering standpoint, the operating layer sits between foundation models and business systems. It governs model selection and routing, prompt templates, retrieval policies, tool registries, identity, rate limits, caching, evaluation harnesses, tracing, and incident response hooks. From an executive standpoint, it is how you turn AI from a set of demos into a repeatable delivery machine.
An agent is a useful lens here because agents force you to solve the hard problems early. Once an AI system plans steps, calls tools, and persists state, you need deterministic controls over what it can do, what it is allowed to see, and what it must record. That set of controls is the operating layer, whether you name it or not.
What Are The Core Components Of An AI Operating Layer (Minimum Viable Platform Stack)?
A minimum viable AI operating layer has six parts: a connector interface for tools and data, a retrieval and data access layer, an orchestration runtime, guardrails and policy enforcement, an evaluation system, and observability with cost controls. Teams often launch with only “RAG plus a chat UI,” then end up backfilling the rest under pressure when reliability drops in production.
Tool connectivity and connectors sit at the front because they determine speed of integration and the blast radius of mistakes. Standardizing tool access reduces one-off adapters and makes governance feasible. MCP is gaining attention as a standard way to expose tools and data sources to LLM applications, reducing bespoke wiring across apps.
RAG and data access must be treated like a product, not a utility. You need indexing rules, chunking policies, freshness SLAs, permission-aware retrieval, and a failure mode that does not leak restricted content. Teams that skip permission-aware retrieval end up with a “helpful assistant” that becomes a compliance incident generator.
Orchestration becomes mandatory the moment you have multi-step workflows: plan, retrieve, call tool, validate, write response, then decide if escalation is needed. The operating layer should offer a standardized orchestration interface so teams can run workflows consistently, enforce checkpoints, and track state across steps.
Guardrails and policy is how you stop AI from turning tool access into uncontrolled automation. Policy enforcement includes input filtering, tool allowlists, output validation, sensitive-data handling, refusal rules, and action gating for high-risk operations. NeMo Guardrails is a concrete example of an open-source toolkit aimed at programmable guardrails between apps and LLMs.
Evaluation is the difference between “it feels better” and “it performs better.” You need offline tests, regression suites, and task-based scoring tied to business outcomes. A real operating layer makes evals easy to run and hard to ignore: release gates, dashboards, and change control for prompts and tools.
Observability and cost controls are what keep multi-step systems supportable. Traces must cover retrieval, tool calls, model calls, post-processing, and policy decisions. Token usage, latency, and error rates should attach to every run so you can find the expensive steps and the fragile connectors fast. MLflow Tracing and OpenTelemetry GenAI semantic conventions are commonly referenced building blocks for this kind of trace-and-metrics instrumentation.
How Do You Build An AI Operating Layer In 30–90 Days (A Practical Blueprint)?
A 30–90 day build works when you commit to a production wedge and harden only what that wedge demands. That sequencing avoids the usual trap: over-building platform abstractions without real load, then finding out the first serious workflow breaks all assumptions.
Start by selecting one workflow that has a visible owner, measurable outcome, and real operational pain. Good candidates are ticket triage with knowledge lookup, internal policy Q&A with citations from approved sources, or sales operations support that reads CRM records and drafts updates. Keep write-actions out of the first wedge unless you already have mature identity controls and audit requirements mapped.
In the first few weeks, implement the path end to end: UI or API, retrieval, one or two tools, and a controlled prompt strategy with deterministic output formats where feasible. Lock down permissions early. Every production incident teams face later starts with permission mistakes, hidden tool behavior, and insufficient logs, not with “prompt quality.”
Weeks 4–8 are where teams separate prototypes from platforms. Add tracing across every step and store it in a system your engineers already use. Make traces queryable by user, workflow, tool, model, latency, and token cost. Add a small but strict evaluation suite built from real interactions, then run it on every prompt and tool change. Treat prompt changes like code changes: reviews, rollout plans, and rollback paths.
Weeks 9–12 is where standardization starts paying. Consolidate connectors behind a consistent interface. If you use MCP for tool exposure, standardize the way servers are configured, authenticated, and permitted. Add role-based access control, approval steps for high-impact actions, and a clear incident playbook for tool failures and data leaks. The operating layer earns trust by reducing operational surprises, not by shipping more features.
A practical delivery rule: ship fewer capabilities, then make them dependable. Teams that cram agents, long-term memory, and dozens of connectors into the first release spend the next two quarters cleaning up operational debt.
Should You Use An Agent Orchestration Tool (LangGraph, Etc.) Or Build It Yourself?
Use an orchestration tool when you need explicit control flow, state management across steps, and checkpoints you can audit. Build orchestration yourself only if workflows are genuinely simple: one retrieval, one model call, no tool calling, no multi-step planning, and no need for durable state.
Agent orchestration becomes real engineering the moment the system must handle retries, tool errors, partial results, and timeouts without producing inconsistent outputs. A mature orchestrator lets you encode the flow as a graph or state machine, run steps deterministically, and attach telemetry and policy checks at every transition. LangGraph positions itself as an agent orchestration product built around reliable agents, state, and controlled flows, which maps directly to what production teams end up implementing anyway.
The strategic point is portability. The operating layer should let you replace orchestration tooling without ripping out connectors, observability, or policy enforcement. Teams get stuck when orchestration and tool wiring are entangled in application code. When that happens, every new workflow costs too much and every bug fix risks unrelated systems.
Pick a workflow representation you can reason about under incident pressure. When an on-call engineer gets paged at 2 a.m., a readable run graph with step-level traces resolves incidents faster than a pile of nested async calls. That difference shows up directly in uptime and support costs.
What Guardrails And Security Controls Are Non-Negotiable For An AI Operating Layer?
Non-negotiable controls fall into five buckets: least-privilege tool access, prompt injection resistance, sensitive-data handling, action gating, and auditability. These are not “nice to have,” since agents plus tools expand blast radius. Once the model can call APIs, a single injected instruction can become an automated misconfiguration or data exposure.
Least privilege starts with tool design, not model behavior. Tools need constrained scopes, tight inputs, and credentials separated by environment, role, and workflow. A deny-by-default tool registry forces explicit approvals. Read-only tools should be the default for early deployments, with write tools protected by approvals and strict logging.
Prompt injection resistance should be treated as a systems problem. You need input filtering, instruction hierarchy rules, and explicit boundaries between untrusted content and system directives. On the tool side, enforce schema validation, allowed operations, and safe defaults. This reduces the chance that untrusted text can smuggle instructions into tool calls.
Sensitive-data handling requires policy enforcement and technical controls: redaction, tokenization, and outbound egress rules for model prompts and logs. Logs should never become a secondary data leak. Treat prompts and completions as sensitive telemetry, and apply retention policies aligned with your broader data rules.
Action gating is mandatory for high-impact operations: deploying code, modifying permissions, issuing refunds, sending external emails, changing pricing, or touching production configurations. Add human approval checkpoints and verification steps that require explicit confirmation, tied to identity. Guardrails tools like NeMo Guardrails are often used as programmable policy layers to enforce these behavioral constraints before and after model calls.
Auditability must cover the full chain: user intent, retrieved documents, tool inputs and outputs, model prompts and completions, policy decisions, and any final actions taken. This is where trace IDs and consistent event schemas matter. OpenTelemetry GenAI metrics conventions highlight the direction the ecosystem is moving: standard fields for token usage, model identifiers, and request attributes so teams can measure and compare runs across tools.
Finally, treat tool servers as part of the threat model. MCP servers, agent plugins, and internal tool APIs must be hardened like any production integration. Vulnerability reports tied to MCP-related tooling are a reminder that the “AI layer” is not just model risk, it is integration risk.
How Do You Measure ROI And Why It Wins Versus Building One-Off AI Features?
An AI operating layer wins on compounding returns: one connector serves many workflows, one policy layer governs many agents, one observability stack supports many teams, and one evaluation harness prevents regressions across the portfolio. One-off features deliver local wins, then create portfolio drag: every change becomes bespoke, every incident is harder to diagnose, and every new workflow repeats the same mistakes.
ROI measurement needs two classes of metrics: product outcome metrics and platform health metrics. Product metrics capture what the business cares about: resolution time, deflection rate, time-to-draft, time-to-close, error rates, and escalation rates. Platform metrics capture whether the AI runtime is becoming more dependable: tool success rate, retrieval hit rate, hallucination-related rework, policy block rate, latency percentiles, and token cost per successful task.
A reliable measurement method is simple: define task success criteria, instrument it at the workflow level, then map it to cost and cycle time. When you can quantify “cost per resolved ticket” or “minutes saved per sales update,” you can compare model routing strategies, caching, retrieval tuning, and prompt updates without hand-waving. MLflow Tracing emphasizes trace capture across steps, which is how you connect the dots between a cost spike and a specific tool or retrieval pattern.
Winning also shows up in change velocity with fewer incidents. With shared evaluation and tracing, teams can ship prompt and tool improvements weekly without burning trust. Without that operating layer, teams ship improvements monthly, and each release carries higher incident risk because nobody can see what changed across the system.
If leadership wants a single sentence: the operating layer turns AI delivery from artisanal engineering into operational engineering, with standard controls and measurable performance.
How Should You Design Tool Connectivity With MCP Without Creating A Vendor Trap?
MCP is often described as a standardized way to connect AI apps to tools and data sources, lowering the integration burden across systems. The strategy that keeps you out of traps is to treat MCP as a connector boundary, not as your entire application runtime. That keeps portability in your hands.
Adopt an internal contract for tools: consistent schemas, strict authentication, deterministic outputs, and well-defined failure modes. Then implement MCP servers that expose those tools cleanly. You still own the important governance pieces: tool allowlists, policy checks, request signing, rate limits, and audit trails. When those controls live inside your operating layer, swapping model providers or orchestration tooling is a bounded project, not a rewrite.
Operationally, standardize how MCP servers are deployed, configured, and monitored. Tool servers need the same hygiene as any microservice: secrets management, network policies, logging, alerting, and patch cadence. Teams often treat tool servers like “plugins,” then get surprised by incidents that look exactly like traditional integration incidents.
Also track ecosystem readiness realistically. Community threads highlight confusion around what “support” means, where MCP is implemented, and how quickly tooling changes. Build with explicit compatibility tests and version pinning. A protocol only helps when the organization can maintain stable contracts across upgrades.
How Do You Operate The AI Layer Day Two Without Burning Your On-Call Team?
Day two operations decide whether the AI operating layer earns long-term adoption. The operating model has to make failures obvious, regressions detectable, and ownership clear. If incident response requires reading raw prompts in scattered logs and guessing what the model did, reliability will collapse under scale.
Start with run-level visibility. Every workflow execution needs a trace that shows retrieval inputs and outputs, tool calls, policy decisions, model prompts, and model responses. Tie it to a user ID, a workflow version, a model version, and a tool version. When a ticket escalates, support staff should be able to pull the trace and see why the system acted the way it did in under two minutes.
Put hard budgets around latency and cost. Set SLOs per workflow: p95 latency targets, maximum token spend per successful run, and error budgets for tool calls. Add automatic degradation modes: if retrieval fails, return a safe fallback response; if a tool errors, skip write actions and request a human. This is how you prevent a single flaky connector from taking down a business process.
Operational discipline also includes release management. Version prompts and tool contracts, run evals before deploy, and roll out changes gradually. Engineers already know how to do this for code, then forget to apply it to prompts and tool servers. The operating layer should make that discipline the default.
Finally, treat data freshness and permissions as monitored signals. If an index falls behind or a permissions mapping breaks, the system may remain “up” while quietly returning wrong results. Alert on these silent failures with freshness checks, sampling audits, and permission-denial anomaly detection.
What Is An AI Operating Layer?
An AI operating layer is the shared runtime that manages tool access, retrieval, orchestration, guardrails, evaluation, and observability for many AI apps.
Build The Layer Once, Then Ship Faster Every Quarter
You build an AI operating layer to stop paying the same integration tax repeatedly: connectors, policy, tracing, evaluation, and orchestration become shared services instead of repeated work. Keep the first 30–90 days tight with a production wedge, then harden what breaks: permissions, tool reliability, auditability, and regressions. Standardize tool connectivity with contracts you own, adopt orchestration that exposes state and checkpoints, and instrument every step so quality is measurable. When ROI shows up in cycle time reduction and lower incident load, adoption accelerates across the organization. The win is operational: dependable delivery at scale, with governance and visibility built in.
References
- No support for MCP within Anthropic (Reddit thread)
- AI agent (Wikipedia)
- Model Context Protocol (MCP) documentation (Anthropic)
- Introducing the Model Context Protocol (Anthropic news)
- MCP unites Claude chat with apps like Slack, Figma, and Canva (The Verge)
- NVIDIA NeMo Guardrails documentation
- NeMo Guardrails (GitHub)
- MLflow Tracing for LLM Observability (MLflow)
- OpenTelemetry semantic conventions for generative AI metrics
- LangGraph agent orchestration (LangChain)
- Report on Anthropic Git MCP server security flaws (TechRadar)

Jay Holstine is a Vistage Chair and veteran tech CEO with 20+ years of experience in SaaS and operations. The founder of SigmaFlow and former CEO of Freightflow, he now leads a Dallas–Fort Worth CEO peer group and advises executives on strategy, process improvement, and scalable growth.